Applied AI, Retrieval-augmented generation2026
RAG Knowledge Assistant
An assistant that answers staff questions grounded in the company's own documents — retrieval first, then a guard-railed LLM, always with citations.
$2k/mo
in staff time saved
−70%
time to find answers
Cited
grounded, no hallucination
The starting problem
LLMs are confident but don't know a company's private, ever-changing knowledge — so they hallucinate, and teams keep losing time digging through scattered docs, wikis, and PDFs.
The system in pictures
Screenshots of the system at work, step by step: what your customer sees, and what your team receives.
- 1.
The workflow

Question → retrieval of the relevant passages → grounded answer with citations.
- 2.
The customer's question
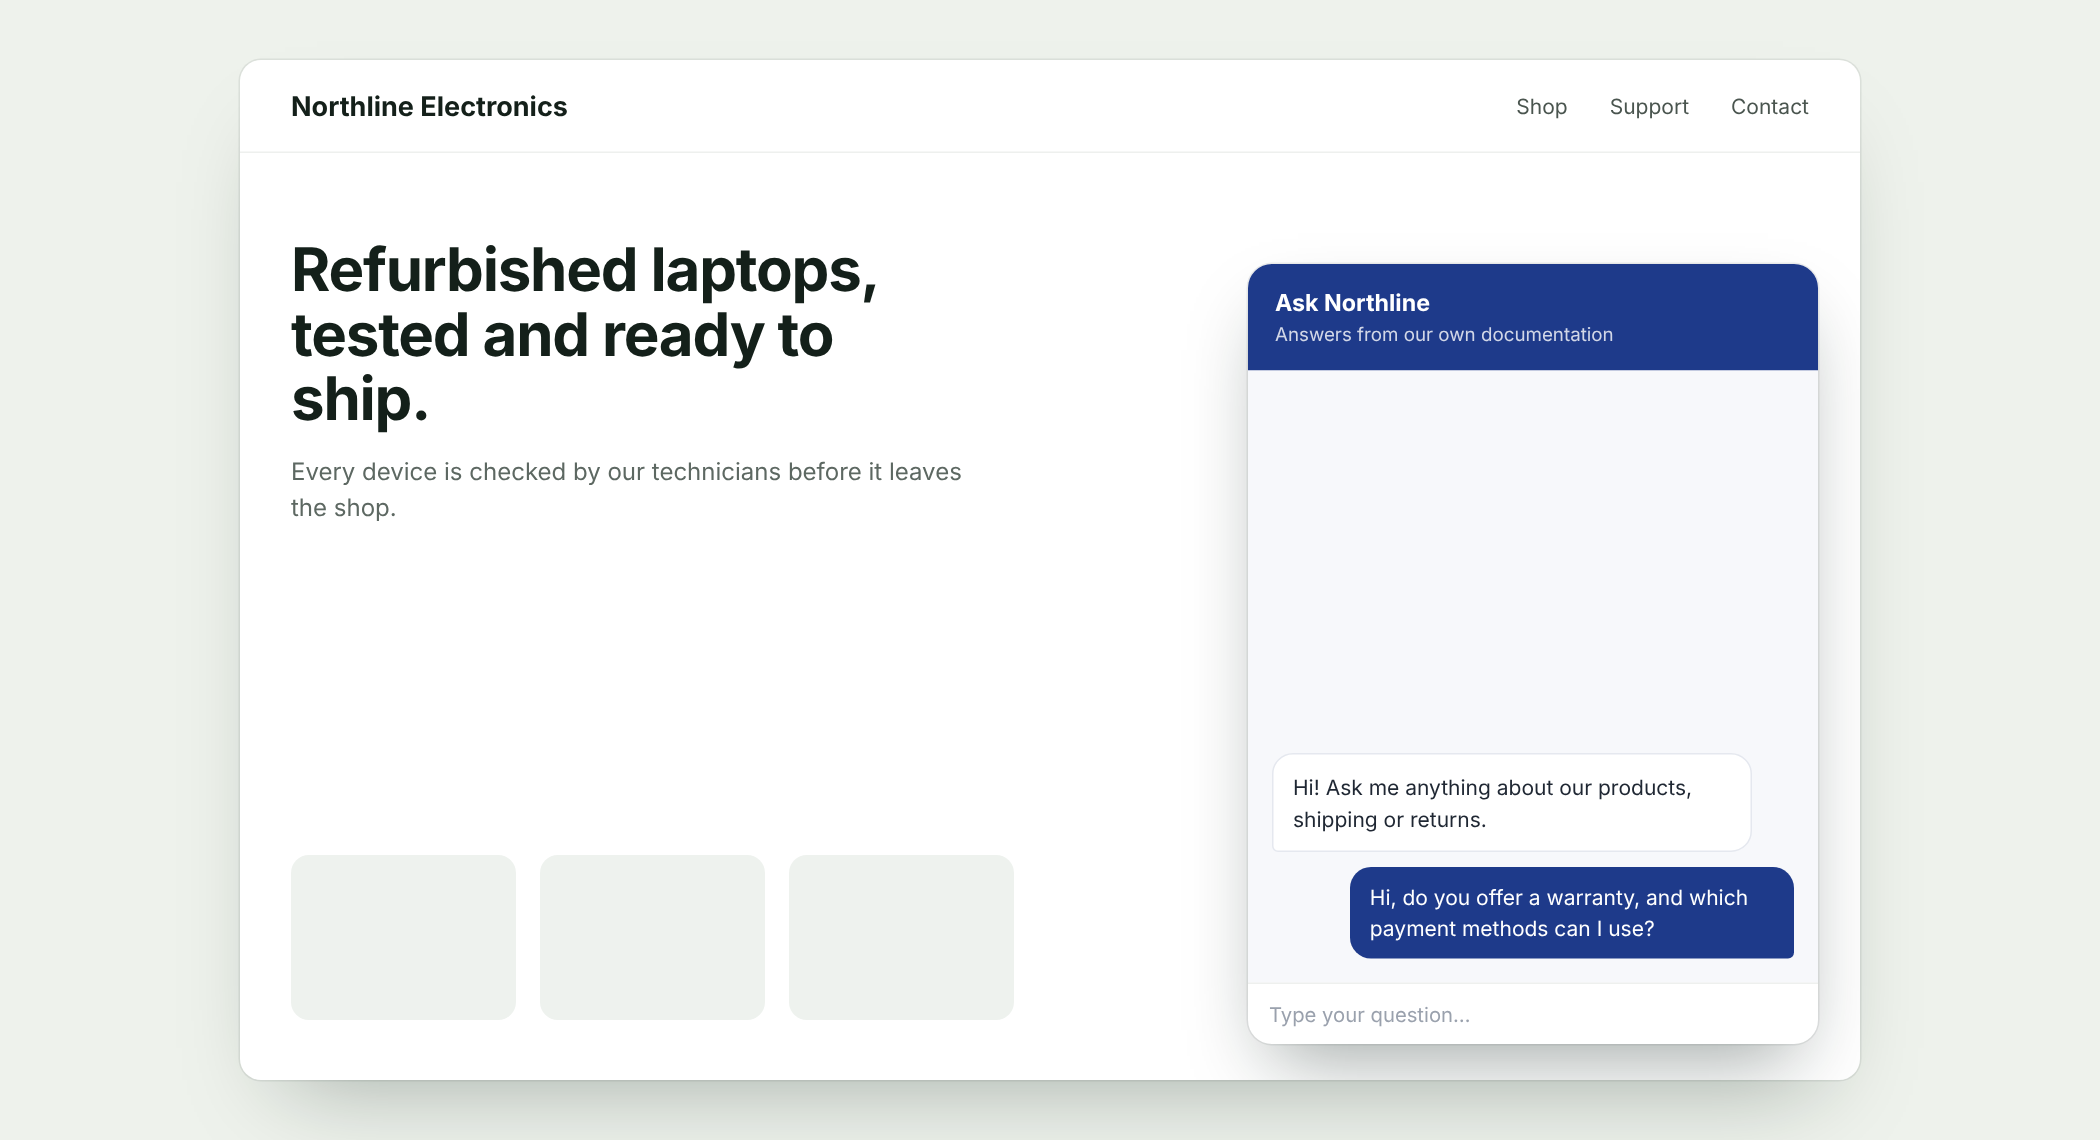
The customer asks a plain-language question (French or English).
- 3.
The sourced answer
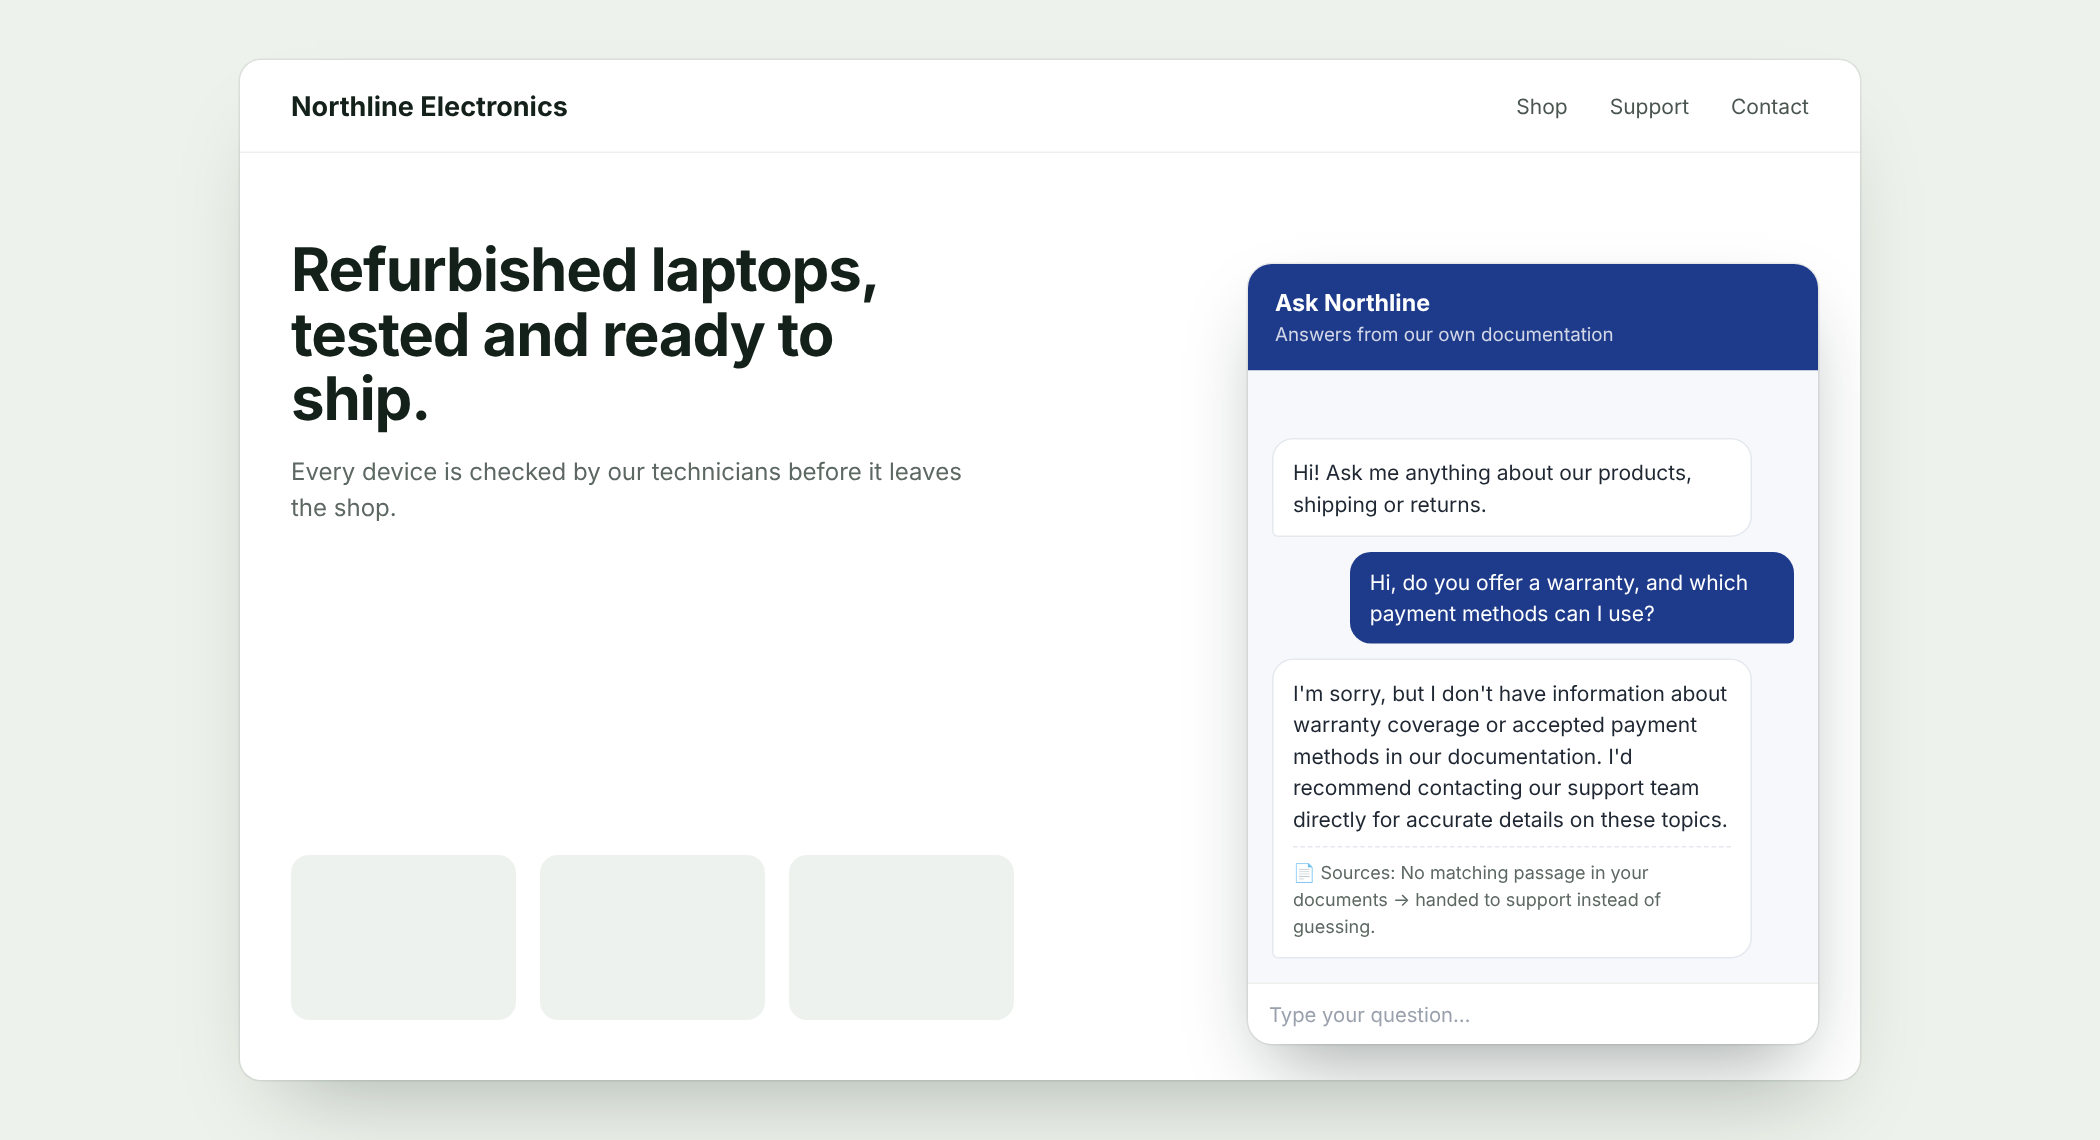
The assistant answers strictly from your documents, with the sources cited, and admits it when it doesn't know.
How it works
What we built
- 1
Documents are ingested, chunked, embedded, and stored in a vector database; a scheduled sync keeps the index fresh as content changes.
- 2
On each question, the system retrieves the most relevant chunks and passes only that grounded context to the LLM.
- 3
The model answers strictly from the retrieved context and returns citations; guardrails make it refuse — rather than guess — when nothing relevant is found.
- 4
Unanswered questions are logged to reveal knowledge gaps, and the assistant is delivered where people already are: Slack and an embeddable web widget.
Highlights
- Grounded, cited answers from your own knowledge — no model fine-tuning required.
- Guardrails prevent hallucination: no relevant context means an honest 'I don't know'.
- Pluggable: swap the model, vector store, or sources without touching the flow.
Tools used
Want the same system for your business?
In 30 minutes, we'll look at whether and how it fits your business.
Next case study
AI Voice Calling Assistant